Redefine technology Cloud, Engineering & Implementation Services Jezero – secure AI platform

Solutions

Jezero – secure AI platform

Move AI from experimentation to secure production in days, not months. Jezero AI combines CACI’s proven AWS cloud foundation with governed AI capabilities, helping organisations innovate without compromising security, compliance or control.

Everything you need to deploy AI securely

Most organisations adopting AI face a difficult choice: move quickly or remain secure. Jezero AI removes that compromise by combining governed AI capabilities with a secure, resilient AWS cloud foundation.

Purpose-built for government, defence, financial services and other regulated sectors, it supports secure deployment across regions and jurisdictions while helping organisations meet data residency and sovereignty requirements.

Every request is authenticated, every action is traceable and every integration is permissioned. This enables teams to move generative and agentic AI from experimentation to production with the auditability, control and assurance their environments demand.

Jezero AI - Creative digital blue circuit grid on blurry office interior background

A proven foundation

Secure by design, ready in under 24 hours

Before Jezero became an AI platform, it was a secure AWS cloud platform. Built on more than a decade of experience delivering large-scale UK Government platforms, that proven foundation is what makes the AI layer trustworthy.

Icon - Shield with a padlock

Security built in from day one

Zero-trust principles, preventative and detective guardrails, automated account vending and continuous visibility are embedded into the platform.

Icon - Illustrative workflow

Well-architected foundations

Built on the AWS Well-Architected Framework using infrastructure as code and self-service models for platform tenants.

Icon - Illustrative workflow

Modular and scalable by design

Choose the components and tooling you need without starting again or compromising the security posture of other tenants.

Icon - Clock melting away

Deployable in under 24 hours

Establish a secure AWS platform for AI in hours rather than spending months engineering the foundation.

Icon - World

Multi-region resilience

Support global, sovereign deployments with multi-region availability in excess of 99.9%.

Icon - Tick with a circle

Licence-free accelerator

Adopt Jezero without ongoing licence fees, hidden catches or long contractual tie-ins.

The Jezero AI layer

One governed platform from model to action

Jezero AI adds governed AI capability directly to the secure Jezero foundation. Every team building on it inherits enterprise-grade security, compliance and operational controls without having to engineer them independently.

Icon - Screen with shield and tick

Secure landing zone

A compliant AWS environment inherited from Jezero’s proven core platform.

Icon - Outline of a person with a tick in a circle

Identity and access

Role-based permissions and policy enforcement across every layer.

Icon - Outline of head with lightbulb

LLM Gateway

Controlled access to approved foundation models, with every request authenticated, checked, logged and routed.

Icon - Shield with three outlines of people and a tick

Platform MCP Server

Define which tools and systems agents can access, the actions they can take and the permissions they operate under.

Icon - Illustrative workflow

Secure data pipeline

Classify, govern and control data before AI interaction while maintaining permissions and lineage.

Icon - Clipboard with check boxes ticked

Audit and observability

Log prompts, outputs, integrations and agent actions for complete operational visibility.

Icon - Magnifying glass with lines and check boxes

Compliance controls

Support alignment with recognised cloud, security, privacy and AI risk frameworks.

Icon - Piece of paper showing an upwards chart with coins and a money symbol

Cost management

Gain usage visibility and apply spend controls from day one.

Icon - Outline of a head with illustrative graph lines

Your AI applications

Build agents, RAG applications and custom workflows on a trusted foundation designed to support what comes next.

Empower developers

Enable innovation without shadow AI

When governed access is unavailable, teams may turn to public AI services, personal accounts or unapproved plugins. This shadow AI bypasses organisational security, compliance and audit controls, increasing the risk of data exposure, lost traceability and inconsistent model behaviour.

Icon - Clipboard with a cog

Approved model access

Give developers controlled access to approved foundation models through the LLM Gateway.

Icon - Outline of head with cogs and arrows in it

Secure IDE integrations

Support development tools such as Claude Code and Kiro within a governed environment.

Icon - Illustrative workflow

Policy-based routing

Route requests according to organisational policy, model approval and workload requirements.

Icon - Multiple pieces of paper with different illustrative graphics

Data filtering

Apply controls before sensitive information can reach a model or external service.

Icon - Illustrative workflow

Prompt and output logging

Retain the evidence needed for audit, investigation and continuous improvement.

Icon - Illustrative workflow

Separated environments

Maintain clear boundaries across development, test and production environments.

Financial governance

Keep AI spend visible and under control

AI governance applies to finance as much as security. Jezero AI helps organisations monitor consumption, control budgets and optimise model selection before uncontrolled usage becomes embedded at scale.

Icon - Upward arrow surrounded by coins and money symbols

Real-time spend visibility

Understand AI usage, model consumption and cost exposure across regions, departments and environments.

Icon - Paper with graph and pound symbol and a calculator

Budget limits and approvals

Set configurable budgets and approval workflows around model access and usage.

Icon - Magnifying glass showing a bar chart

Automated thresholds

Trigger controls when consumption reaches defined organisational limits.

Icon - Magnifying glass showing a warning symbol

Usage anomaly detection

Identify abnormal, inefficient or high-risk activity through continuous monitoring.

Icon - Outline of a head with a light bulb in the middle

Intelligent model routing

Direct workloads to the most cost-effective approved model that meets performance and policy needs.

Icon - Cupped hands with a money symbol in the middle

No ongoing licence fees

Build the business case without adding recurring Jezero licence costs.

Built for regulated industries

Secure AI for environments where trust is non-negotiable

Icon - Employee badge

Government

Deploy AI in line with public sector security, compliance and sovereignty requirements.

Icon - Surveillance style camera

Defence

Operate mission-ready AI within highly assured, classified and sovereign environments.

Icon - Outline of three people

National security

Support sensitive, mission-critical workloads with enhanced isolation and access controls.

Icon - Money with the world

Financial services

Apply governed AI in line with regulatory, audit and operational resilience requirements.

Icon - Stethoscope

Healthcare

Protect sensitive data while enabling compliant AI across critical clinical operations.

Icon - Lightbulb with a tick

Legal and law enforcement

Maintain confidentiality, control and auditability in high-trust environments.

Proven in high-assurance environments

Trusted by NATO and the UK Home Office

Jezero AI is delivered by CACI, through IdentityE2E, drawing on decades of experience designing and operating secure, mission-critical cloud platforms for government and highly regulated organisations.

Jezero AI is designed to support recognised security, privacy, cloud and AI risk frameworks, including NCSC Cloud Security Principles, ISO 42001, NIST AI RMF, the EU AI Act, GDPR, the AWS Well-Architected Framework and CIS Benchmarks.

Icon - Illustrative workflow

Award-winning delivery

Delivered the award-winning EBSA platform for the UK Home Office.

Icon - Person showing a chart on a display board

Proven deployments

Jezero-TSE supports NATO and Home Office workloads.

Icon - Lightbulb with a tick

AWS TSE recognition

First UK organisation admitted to the AWS Vetted Partner Programme.

Icon - Paper with a list and ticks

AWS expertise

Delivered by an AWS Premier Tier Partner.

Icon - Shield with a padlock

Security crendetials

Supported by Cyber Essentials and ISO 27001 certification.

Icon - Desktop computer with a security padlock and a cursor hovering near

Public sector access

Available through Crown Commercial Service supplier routes.

Take AI from experiment to secure production

See how Jezero AI can help your organisation deploy governed AI in days, not months, with the security, compliance and control regulated environments demand.

FAQs

Answers to common questions about Jezero AI.

Jezero AI is a secure AWS cloud platform for deploying governed generative and agentic AI. It combines Jezero’s proven secure landing zone with identity and access controls, an LLM Gateway, a Platform MCP Server, governed data pipelines, audit and observability, compliance controls and cost management. This gives regulated organisations a ready-made foundation for moving AI from experimentation into production without building every security and governance component from scratch.

Jezero AI is designed for organisations that cannot compromise on security, compliance, sovereignty or auditability. This includes government, defence, national security, financial services, healthcare, legal and law-enforcement environments. Its modular architecture also allows organisations to tailor the platform to their tooling and deployment requirements while retaining common security guardrails and operational controls.

The Jezero secure AWS foundation can be deployed in under 24 hours. This allows organisations to establish the core environment for governed AI in days rather than spending months engineering landing zones, policies, controls and platform tooling from scratch. The time required to launch a specific AI application will still depend on its data, integration, assurance and use-case requirements.

Jezero AI applies security and governance across infrastructure, data, models and agent actions. It supports data classification and tagging, network segmentation, private endpoints, role-based access, policy enforcement and governed data pipelines. Requests pass through a controlled LLM Gateway, while prompts, outputs and agent actions can be logged to provide traceability and reduce the risk of sensitive information reaching unapproved services.

The LLM Gateway provides a controlled interface between users or applications and approved foundation models. Every request can be authenticated, policy-checked, logged and routed according to organisational requirements. This helps prevent unauthorised model use, reduce data leakage, maintain an audit trail and direct workloads towards an approved model that balances security, performance and cost.

The Platform MCP Server defines which tools, data sources and systems AI agents can access, which actions they can take and the permissions under which they operate. Combined with secure model routing, governed data pipelines and action logging, this allows organisations to use agentic workflows within controlled boundaries, with human oversight where required and a traceable record of activity.

Yes. Jezero AI gives developers governed access to approved models and secure IDE integrations, reducing the incentive to use personal accounts, public AI services or unapproved plugins. Policy-based routing, data filtering, prompt and output logging, and separation across development, test and production environments allow teams to experiment and build while organisational security, compliance and cost controls remain in place.

Jezero AI is designed to support recognised security, privacy, cloud and AI risk frameworks, including NCSC Cloud Security Principles, ISO 42001, NIST AI RMF, the EU AI Act, GDPR, the AWS Well-Architected Framework and CIS Benchmarks. Its controls include role-based access, policy enforcement, data classification, private endpoints and detailed logging of prompts, outputs, integrations and agent actions. Specific compliance obligations should be assessed against each organisation’s use case and operating environment.

The platform provides visibility into model usage and cost exposure across teams, regions and environments. Organisations can configure budget limits, approval workflows and usage thresholds, monitor anomalies and route workloads to cost-effective approved models that meet performance and policy requirements. Jezero is also a licence-free accelerator, so there are no ongoing Jezero licence fees to add to the business case.

Jezero-TSE is a highly assured variant of the Jezero platform for sensitive and classified workloads. Built with AWS Trusted Secure Enclaves, it adds enhanced network isolation, stricter access controls, automated compliance remediation and reference architectures for national security, defence and law enforcement. Jezero AI can be delivered on a Jezero-TSE foundation when an organisation requires this higher level of assurance.

Solutions

Cydonia – face biometric platform

Verify and identify people at speed and scale. Cydonia combines independently benchmarked face recognition with a secure, resilient cloud platform, helping organisations establish trusted identity without compromising accuracy, security or accountability.

A complete platform for trusted identity

Most face-matching solutions provide an algorithm. Cydonia provides a complete biometric identity platform, bringing together advanced biometric technology, secure cloud architecture and operational tooling.

Built on Jezero, CACI’s secure AWS cloud platform, Cydonia combines cloud guardrails and network controls with a resilient Kubernetes foundation. Its underlying technology is independently benchmarked through recognised NIST and DHS evaluations.

Deploy Cydonia as a fully managed SaaS service or within your own AWS account. Its vendor-agnostic architecture can also support additional biometric algorithms as your requirements and the technology evolve.

Cydonia - Business people that work together in office. Concept of teamwork and partnership

Why Cydonia

Perform under real-world pressure

Cydonia combines speed, scale and operational resilience so biometric identity services can keep working when volumes rise, imagery is imperfect and every decision matters.

Icon - Person with bar chart next to them and upward arrow

Scale without compromise

Support virtually unlimited concurrency and galleries containing hundreds of millions of records without sacrificing matching accuracy.

Icon - Merge of clock and cog

Make decisions faster

Deliver more than one million matches per second per core, reducing processing time and user waiting.

Icon - Cog with upwards arrow going through it

Perform beyond the laboratory

Maintain accuracy across varied lighting, angles, face coverings, low-quality imagery and profile views.

Icon - Bar graph with upward arrow

Respond to demand

Scale compute programmatically in real time, maintaining performance during peaks and reducing cost during quieter periods.

Icon - Magnifying glass with the outline of three people

Manage complex galleries

Use distributed biometric and vector data, sub-galleries and attribute-based filtering to narrow searches efficiently.

Icon - Outline of a head being opened and shapes going in

Evolve without lock-in

Adopt a vendor-agnostic platform designed to integrate further biometric algorithms when they meet CACI’s testing requirements.

Full identity AI capability

Protect identity across physical and digital interactions

Cydonia brings together the complementary checks needed to establish whether a person is who they claim to be, detect manipulation and apply the right level of assurance to each interaction.

Icon - Outline of three people and one being behind a magnifying glass

Face recognition

Support fast 1:1 verification and large-scale 1:N identification, with face detection, landmarks, image-quality analysis and dynamic gallery search.

Icon - Paper with magnifying glass

Passive liveness detection

Confirm that a real person is present from a standard selfie or webcam image, without extra hardware or user actions.

Icon - Outline of person with a cross in a circle

Deepfake detection

Identify identity-swap, expression-swap and fully synthetic faces from a single image or video frame.

Icon - Outline of a head with a light bulb in the middle

Privacy-preserving age estimation

Estimate age from one face image to support age-appropriate access without requiring full identity verification.

Icon - Outline of a person

Face attribute analysis

Add context through automated analysis of attributes such as headwear, eyewear, face coverings and image conditions.

Icon - Surveillance style camera

Streaming video integration

Apply face, person and vehicle detection and tracking to existing RTSP video feeds and camera infrastructure.

Powered by proven Paravision technology

t reviews and live trials with AWS, CACI selected Paravision Search for its accuracy, scalability and cloud-native performance.

Paravision’s facial recognition technology has been independently evaluated by NIST for more than five years, consistently ranking among the leading global performers.

It also supports Cydonia’s liveness and deepfake detection capabilities, helping protect against physical and digital identity fraud.

Cydonia - Modern Access Control System with Smartphone Integration at Security Entrance

Built for demanding use cases

One platform, multiple identity journeys

Icon - World

Government and national security

Support identity cards, immigration, watch-listing and passport services where accuracy, resilience and compliance are critical.

Icon - Map and magnifying glass

Travel and borders

Enable contactless identity journeys across eGates, airport checkpoints and border programmes.

Icon - Outline of a person with three ticks next to them

Digital identity

Verify people quickly for banking, retail and payments while balancing fraud prevention with user experience.

Icon - Money with the world

Payments and retail

Authenticate in-person and online transactions across mobile payments, loyalty programmes and ecommerce.

Icon - Hand holding a shield with a tick

Physical security

Deliver touchless access control, visitor management, time and attendance, and video-security integrations.

Icon - Two speech bubbles

Live events

Strengthen access validation, ticketing and entry at conferences, concerts and sporting venues.

Responsible by design

Biometric capability with clear safeguards

Powerful biometric technology must be deployed responsibly. Before Cydonia is licensed and provisioned, the intended use must be clearly defined and pass a stringent approval process against CACI’s use-case standards and Paravision’s published AI Principles.

Icon - Shield with a padlock

Ethically trained

Use diverse, properly consented training data and independent benchmarking to identify and address performance gaps.

Icon - Paper with a list and ticks

Conscientiously deployed

Vet customers, partners, countries and proposed use cases before access to the platform is approved.

Icon - Outline of head with lightbulb

Human accountability

Require human review before consequential decisions and prohibit use in lethal autonomous weapons systems.

Bring secure biometric capability into operation faster

See how Cydonia can help you verify and identify people accurately at scale, protect against physical and digital manipulation, and deploy on a secure platform built for real-world demands.

FAQs

Answers to common questions about Cydonia.

Cydonia is CACI’s advanced biometric identity platform. It combines face recognition and wider identity AI capabilities with the security, resilience and scalability of Jezero, CACI’s secure AWS cloud platform. Rather than supplying only a matching algorithm, Cydonia provides an integrated environment for biometric enrolment, verification, identification, liveness detection, deepfake detection, age estimation and operational management.

Cydonia can be delivered as a fully hosted, managed SaaS service or deployed directly into an organisation’s own AWS account. The underlying platform runs natively on Kubernetes and supports auto-scaling, resilience and self-healing. Its flexible architecture can be tailored to specific service levels and use cases while retaining secure cloud guardrails and operational controls.

In 1:1 verification, Cydonia compares a person’s biometric image with one claimed identity to confirm whether they match. In 1:N identification, it searches a gallery of many enrolled identities to find potential matches. Cydonia supports both models, from straightforward digital identity checks to large-scale searches across galleries containing hundreds of millions of records.

Passive liveness detection helps identify physical presentation attacks such as printed photographs, screens and masks from a single selfie or webcam image. Deepfake detection addresses digital manipulation, including identity swaps, expression swaps and fully synthetic faces. Together, these capabilities help protect identity journeys across both physical and digital channels without requiring specialist capture hardware.

Cydonia is designed to maintain performance beyond controlled laboratory conditions. Its capabilities include face detection, landmark identification and image-quality analysis, with matching designed to handle differences in angle and lighting, profile views, face coverings and lower-quality images. Live image-quality feedback can also help users correct sharpness, position, illumination or frontality before submitting an image.

Cydonia is designed for high-volume programmes and supports virtually unlimited concurrency, galleries containing hundreds of millions of records and programmatic auto-scaling. Published performance figures include enrolment of 50 million identities in under 3.5 hours and 1.4 million matches per second per core on specified Intel Xeon hardware. Actual performance will depend on the deployment architecture, workload and service requirements.

CACI requires the intended use of Cydonia to be defined and approved before the platform is licensed and provisioned. The review considers CACI’s use-case standards and Paravision’s AI Principles, including consented and diverse training data, independent benchmarking, customer and partner vetting, restrictions on countries and use cases, human review for consequential decisions and a prohibition on lethal autonomous weapons applications.

From AI ambition to AI readiness: Why data foundations matter more than models

In this Article

AI is everywhere. Readiness is not.

AI ambition is no longer the problem for most organisations: strategies have been written, platforms procured and pilot use cases demonstrated. The challenge now is translating early success into AI that can be trusted and deployed at scale. 

Why? The model usually is not the blocker. The data is. 

As the first blog in our series on building strong data foundations for AI, we outline the process you would take to move from AI ambition to readiness. Each blog will explore a real data fragility, why it blocks AI and what “good” looks like in practice. 

Common data issues that hold AI back

Data is often hard to locate, inconsistently described, poorly governed and difficult to trust. This makes it significantly harder to use AI safely and with confidence. Simply put, bad data leads to bad AI.  

Organisations rarely fail because they picked the wrong model. They fail because they overestimate how ready their data estate really is. We tend to see the same recurring failure modes: 

  • Inconsistent naming and structure: Datasets that overlap but are described differently 
  • Incomplete or missing metadata: Making it difficult to understand what the data represents
  • Unclear ownership and stewardship: No single point of accountability for data quality
  • Weak lineage and provenance: Limited visibility of where data originated or how it has changed
  • Duplication and fragmentation: Multiple versions of “the same dataset across teams or platforms.

These problems are not operational irritations; they directly affect AI outcomes:

  • Models are trained on inconsistent or misunderstood inputs 
  • Retrieval systems return irrelevant or incomplete context 
  • Outputs become harder to explain and defend, particularly in regulated environments 

The result? Teams end up doing data clean-up instead of building working AI. 

FAIR as a practical starting point

The FAIR Guiding Principles (Findable, Accessible, Interoperable, Reusable) were introduced in 2016 to make data easier for both humans and machines to find, share and reuse. FAIR consists of fifteen principles which aim to make data: 

  • Findable: Ensuring data and metadata is discoverable by humans and machines. 
  • Accessible: Data and metadata are accessible with open protocols (with authorisation and authentication applied as necessary) and metadata remains when data is no longer available to support historic auditability and provenance.
  • Interoperable: Data and metadata use a formal, shared and broadly applicable language, including vocabulary that follows FAIR principles. Data and metadata may reference other data or metadata. 
  • Reusable: Domain relevant and richly described metadata should be reusable and, importantly, associated with data provenance.  

What people often miss is that FAIR is not about making data easier for people to browse, but about making it easier for systems to work with. As data volume, complexity and speed increase, humans increasingly rely on computational support. FAIR ensures those systems operate reliably. Its growing relevance to AI stems from its ability to address many challenges organisations face when trying to scale AI. 

This is integral if you want AI to work beyond a demo. If data cannot be reliably understood by machines, pipelines break down. Feature engineering becomes inconsistent. Joining data across the organisation becomes slow and expensive. AI systems become brittle and hard to scale. 

For organisations beginning their AI journey, FAIR changes the question from “Do we have data?” to “Can our systems reliably find, understand, combine and reuse it with minimal human intervention?” 

Why FAIR is necessary, but not sufficient

FAIR provides a practical foundation for describing, discovering and reusing data. It helps with some of the basics, but it does not guarantee that the data is accurate, current or fit for real-world use. 

FAIR solves discoverability, not fitness

FAIR ensures data can be found, accessed and understood. This removes many barriers preventing effective data discovery and consumption, enabling trusted data reused across systems, encouraging: 

  • Rich, structured metadata 
  • Consistent identifiers and references 
  • Standardised formats and vocabularies 
  • Clear provenance and licensing. 

But it does not answer key questions: 

  • Is the data accurate and complete? 
  • Is it current and maintained? 
  • Is it actually suitable for the decision or process it will support? 
  • Can it be trusted when the decision really matters? 

In AI systems, poor data quality directly affects outcomes. Systems trained on incomplete or inaccurate data will learn and reproduce weaknesses. Poor data requires AI systems to resolve data issues before use, requiring more processing power and tokens, leading to less accuracy and more expensive results. 

It is entirely possible to have data that is technically FAIR, but still: 

  • Contain significant quality issues 
  • Be poorly governed in practice 
  • Be unsuitable for model training or inference. 

From an AI perspective, FAIR-compliant data may still produce unreliable predictions, bias into model outputs or undermine confidence when it comes to AI-driven decisions. Discoverability in isolation will not make data AI-ready. 

AI introduces additional demands beyond FAIR

Bad data is a problem for analytics. It becomes an even bigger problem when you add AI. 

  • Consistency at scale: Small inconsistencies that are tolerable in reporting can significantly degrade model performance 
  • Traceability and explainability: The ability to demonstrate how outputs were derived, particularly in regulated environments 
  • Continuous maintenance: Data pipelines must remain stable over time, not just be discoverable at a point in time 
  • Operational integration: AI also depends on data being available inside the tools and processes people actually use. 

FAIR supports elements of this, particularly around metadata and provenance, but on its own, it cannot check for data accuracy, offer ongoing data management, monitor data quality slips or integrate data into production systems. 

Without these, you cannot rely on the data when AI moves into real-world use. 

Governance, stewardship and architecture still matter

Organisations that successfully move beyond pilots know FAIR is only the starting point. They also prioritise: 

  1. Clear responsibility for maintaining data accuracy and usability 
  2. Rules and controls that manage risk without slowing delivery 
  3. Ongoing work to improve and maintain data quality 
  4. A technical set-up that lets data move consistently between teams and tools. 

Without these, FAIR initiatives can stall. Metadata may be defined but not maintained. Standards may exist but not be adopted consistently. Catalogues may be populated but not trusted. 

Case study: Enabling FAIR foundations for a public sector client

The challenges described so far are not theoretical, they are typical of large, data-rich organisations operating in complex, regulated environments. 

CACI worked with a public sector client, producing terabytes of data daily to address these challenges by establishing a standardised metadata model aligned to FAIR principles and tailored to organisational and domain needs. 

Hundreds of datasets were produced and consumed across different domains, supporting everything from operational to long-term analytics workloads for public and private sector consumption. These datasets vary in structure, purpose and lifecycle, ranging from highly-structured, rapidly changing, high-volume data to bulk, unstructured, long-lived records. 

Before the introduction of standardisation, this scale and diversity created familiar issues: 

  • Difficulty finding relevant data across the estate 
  • Inconsistent ways of describing datasets and their context 
  • Challenges understanding lineage, provenance and appropriate use 
  • Barriers to interoperability, particularly with international partners. 

Applying FAIR through metadata standards

A standard metadata record format was defined using JSON to create a consistent, machine-readable structure for describing datasets across the organisation. This gave the client a practical way to put FAIR into use: 

  • Findable: Metadata was structured to support discovery based on key attributes such as temporal range, spatial coverage, data type and source. This streamlined finding data without depending entirely on manual search. 
  • Accessible: Access controls were incorporated into the metadata model, allowing datasets to be discoverable even where access was restricted, for example, for sensitive domain-related data. This reflects a common requirement in government contexts: keeping the right controls in place while still helping people find what exists. 
  • Interoperable: Metadata was aligned to international standards, enabling data to be shared and understood across organisational and national boundaries. This is a concrete example of interoperability beyond a single organisation. 
  • Reusable: The inclusion of provenance, lineage and structural metadata (such as measurement units and scientific context) supported reuse across different use cases and user groups.  

Beyond FAIR: Organisational and technical change

For this client, implementing FAIR required: 

  • Collaboration across stakeholders to agree upon common definitions and structures 
  • Balancing standardisation with flexibility, ensuring the model could extend over time 
  • Embedding metadata practices into existing processes, rather than treating them as a separate activity. 

Rolling out the new standard resulted in a more consistent and user-friendly data discovery experience, improving on previous data product catalogue attempts seen through increased consumption and fewer queries from internal and external consumers. It also re-focused governance on policies that have demonstrable benefit across the organisation. 

How CACI can help you achieve data readiness

To help organisations tackle many of the challenges explored throughout this series, we have created a new Data Management AI Accelerator that rapidly establishes trusted data foundations through:  

  • AI-enabled data cataloguing 
  • Governance 
  • Classification 
  • Access management. 

This simplifies the understanding, security and governance of data at scale. By improving data visibility, accessibility and control, you can remove some of the key barriers that prevent AI from moving beyond experimentation and into real-world adoption. 

Because successful AI is not just about what you build, but whether it can be trusted, adopted and scaled. 

In the next blog, we will explore how organisations can begin to assess trust at scale, from ethics to explainability, and what it takes to apply AI with confidence in real-world environments. 

If you would like to understand where your organisation sits today or learn more about our Data Management AI accelerator, contact us to discuss your AI ambitions and how you can scale them. 
Case study

How CACI built a secure, scalable AI sandbox for a financial services company to modernise data capabilities

Summary

A UK financial services company partnered with CACI to design and implement a secure AI sandbox for early-stage experimentation. Operating within strict regulatory and security constraints, the company needed more than a standard environment; they required a tightly controlled, repeatable approach that balanced innovation with governance. CACI delivered a secure-by-design, fully scripted sandbox aligned to these requirements, enabling safe experimentation, faster onboarding and a scalable foundation for future AI initiatives.

Company size

500 – 1000

Industry

Financial Services

Challenge

Introducing an AI sandbox was not a straightforward technical exercise for this company. It required navigating the realities of a highly regulated environment, where security, compliance and control are non-negotiable.

While they had strong data science capabilities, there was no established framework for safely experimenting with AI in a way that met stringent security and regulatory standards. The challenge was therefore twofold: enabling innovation while maintaining absolute confidence in security and governance.

Icon - Jigsaw puzzle pieces

Model deployment constraints

The environment also needed to provide a simple route for deploying AI models as web apps to make ML decisioning available to a wider audience in a user-friendly way.

Icon - Illustrative workflow

Evolving platform capabilities and configurations

This required careful interpretation to ensure the environment was stable, supportable and aligned to best practice.

Icon - Magnifying glass with upward line

Minimal R support

While Python was well supported, R integration was weak for reading data despite being critical for the client. They needed a stable and repeatable environment that could work day-to-day.

Icon - Money symbol with arrows

Cost visibility and control

These were critical, especially in a sandbox model where experimentation can quickly scale without clear guardrails.

Solution

CACI approached this as a security-first architecture challenge, designing a sandbox that would enable AI experimentation while meeting the company’s strict regulatory and governance requirements.

Secure-by-design, enterprise-grade architecture

  • A standard Azure Machine Learning deployment can be created with only a handful of CLI commands. To satisfy the client’s security requirements, we designed a fully private architecture with no public endpoints, adding virtual networking, private DNS, network security controls, private connectivity and secure access mechanisms. The resulting infrastructure was codified in over 1,300 lines of Bicep.

Fully scripted, repeatable infrastructure (Infrastructure-as-Code)

  • Every element, from network configuration to compute provisioning, was defined in code and version-controlled. This ensures environments can be reliably recreated, audited and scaled without deviation or manual risk.

Tightly governed, private environment

  • The sandbox was built with private endpoints and no public network exposure, embedding security from the ground up and ensuring alignment with the client’s stringent data protection requirements.

Integrated, flexible tooling for users

  • The environment supports Azure Machine Learning Studio alongside VS Code, Jupyter and RStudio, enabling both data scientists and wider teams to work effectively within a single, governed ecosystem.

Enablement through clear guidance and documentation

  • CACI delivered practical Quickstart guides and documentation, equipping the company’s teams to confidently use, extend and replicate the environment, turning a one-off build into a repeatable organisational capability.

Results

The outcome was a working sandbox with a trusted foundation for AI innovation within a highly regulated context.

By CACI introducing a fully repeatable, code-driven approach, the company can now create new environments quickly and consistently, without reintroducing risk. This has significantly reduced the operational overhead associated with setup while improving alignment across development, test and future production environments.

Just as importantly, the solution brought clarity and control. Version-controlled infrastructure and standardised configurations provide full transparency over how environments are built and managed, supporting auditability and governance processes.

From a user perspective, the improved tooling and clearer workflows have made it easier to work with models, accelerating experimentation and enabling broader engagement beyond purely technical teams.

The impact has been both immediate and strategic. The client not only successfully established a secure sandbox but also gained a reusable approach that can support future AI use cases with confidence.

This confidence was reflected in continued engagement, with the company extending CACI’s support and exploring how the sandbox can underpin additional, production-facing initiatives.

The client has now gained

  • Secure, private AI sandbox aligned to strict regulatory requirements
  • Fully scripted, reusable infrastructure (Infrastructure-as-Code)
  • Integrated development tooling supporting both Python- and R-based workflows
  • Version-controlled environments, data and models
  • ML flow-enabled modelling pipelines
  • Simplified source control and deployment workflows
  • Comprehensive documentation and Quickstart guides
Male IT Specialist Holds Laptop and Discusses Work with Female Server Technician, they are standing in a server room together

Introducing AI in Certa: trusted AI care management software

In this Article

Certa now includes AI care management software capabilities designed to help care providers work more efficiently, analyse complex data more quickly and reduce the time spent on administrative tasks. Built on cloud-based infrastructure, Certa leverages advanced AI services alongside your operational data to deliver improved outcomes for you and your clients.

The AI landscape is rapidly evolving and Certa’s product roadmap features ongoing ideas for the incorporation of AI for the betterment of the software and person-centred care outcomes. As with every Certa release, we work closely with our customers throughout the development process. AI is no different.

AI care management software you can trust

Trust is essential when using AI care management software. Certa’s AI only ever calls upon your data from within Certa, removing the risk of hallucination and error. This means you can rely on the accuracy of the answers Certa provides.

Every AI release within Certa is signed off by CACI’s Clinical Safety Officer and Certa is DCB0129 compliant, providing complete peace of mind when using its AI capabilities

Find important information faster

Care records often contain large amounts of information. Finding the information you need, when you need it, can be time consuming. Certa’s AI care management software tools help users identify and access important information within complex records instantly, including client risks, needs and priorities. 

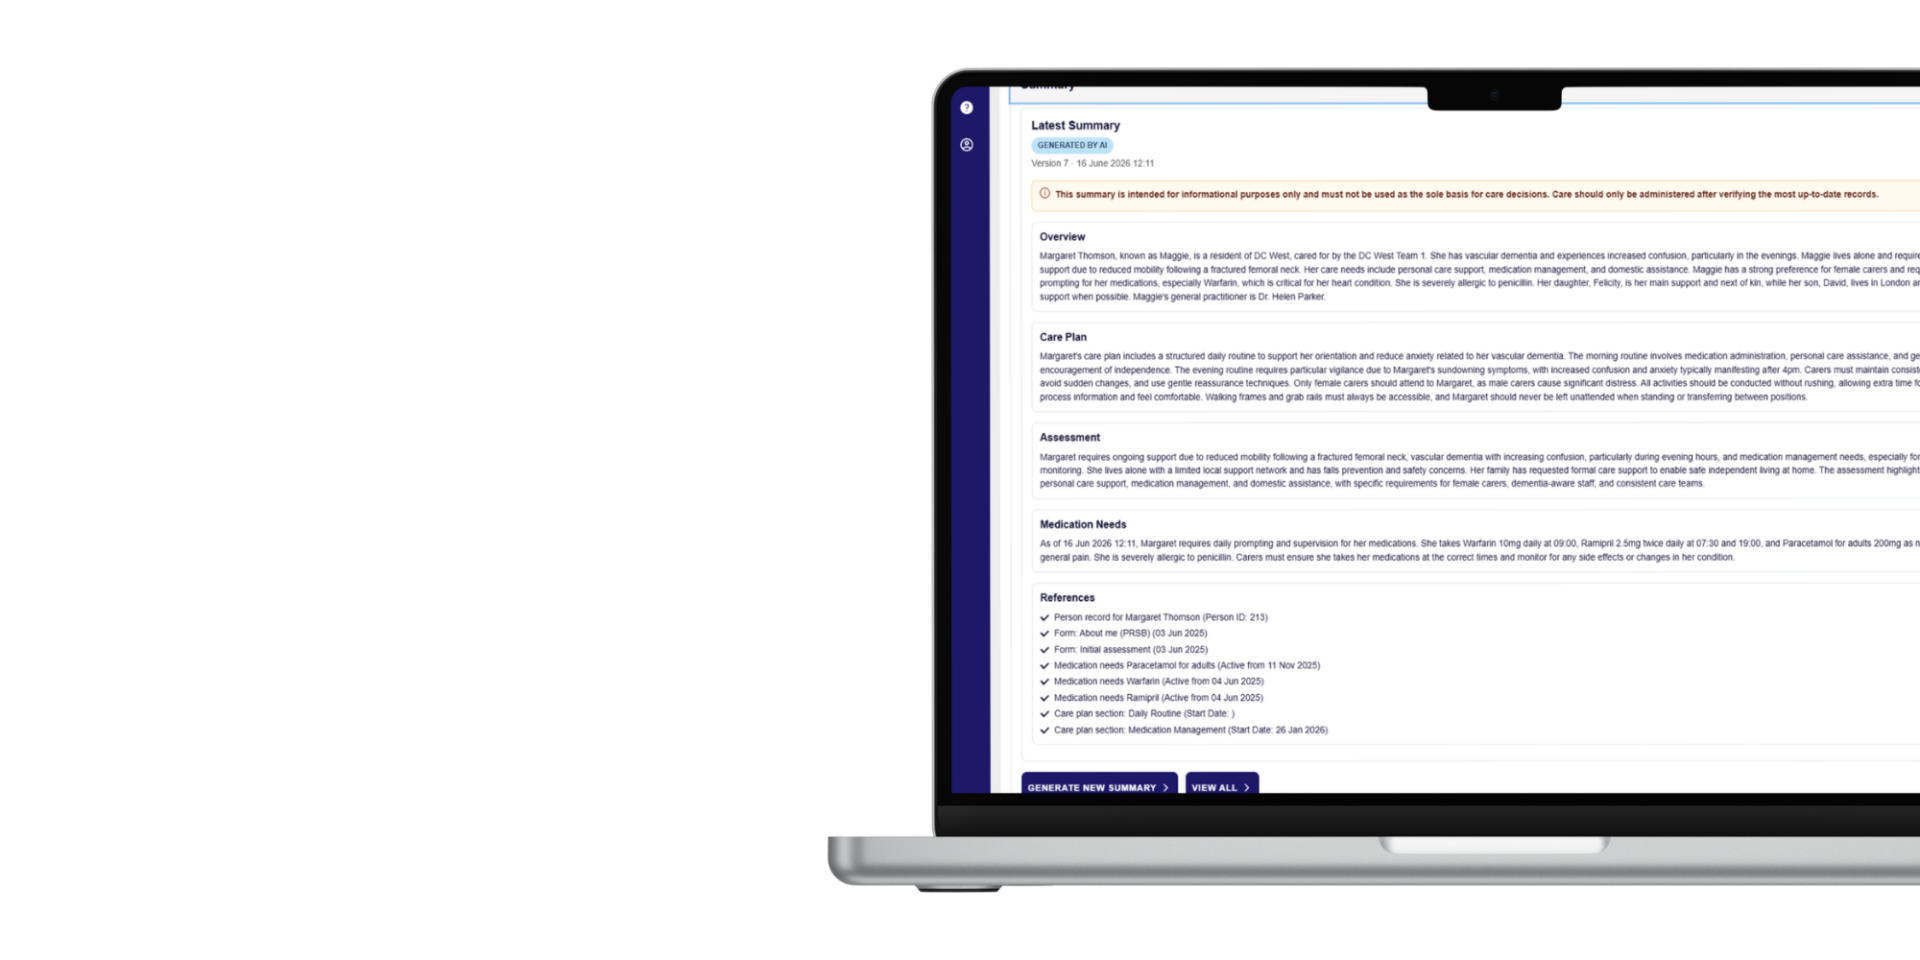
Certa’s AI client summary generates concise overviews, describing a client and their needs using information captured within their client record, assessments, care plan and medication needs. This helps users understand client needs quickly, without creating bespoke reports and sifting through data. 

Reduce administrative effort

Documentation is one of the biggest drains on care workers’ time. Certa’s AI Care Notes feature, which is scheduled for release towards the end of 2026, will assist support workers in capturing care records more quickly and accurately, while also helping back-office staff keep assessments and care plans current through AI-assisted transcription and form completion. Less time on paperwork. More time on care. Without cutting corners on the record that matters. 

As the data called upon only exists within your Certa system, the accuracy of its output will reduce the risk of human error. This will help to enhance the accuracy and consistency of your reports, providing trustworthy information that users can rely on, whilst at the same time reducing the administrative burden. 

Smoother rostering

As well as reducing the administrative burden in report curation via AI, Certa’s sophisticated algorithms also assist schedulers in matching care workers to clients. When it comes to rostering and schedules, an algorithm offers better support than AI as there’s less interpretation of the process – your rules, your roster. This is particularly beneficial when it comes to short-term and last-minute changes. If a carer is absent from work, how can you best restructure your care services to ensure that all clients receive the care they need? 

Certa can instantly suggest changes based on the availability, experience and geographic location of the carer at any given moment with the needs and preferences of the client. This reduces the time spent matching this information manually, leaving schedulers to double check suggestions reducing the impact of inevitable late changes. 

Continuously evolving AI care management software

Certa can instantly suggest changes based on the availability, experience and geographic location of the carer at any given moment with the needs and preferences of the client. This reduces the time spent matching this information manually, leaving schedulers to double check suggestions reducing the impact of inevitable late changes.

Conclusion

There are understandable concerns around the use and future reliance on AI, particularly in safety critical environments such as care providers. Simply, mistakes cannot be tolerated. We’ve designed Certa’s incorporation of AI to mitigate these risks, but also to work alongside and support human care.

Care is a very human service and is not something that can ever be replaced by AI. Our intention is for it to support this human delivery by providing tools that help to keep services on track, even in times of strain. By helping to reduce administrative tasks, Certa and its AI care management software tools will free up time to be focussed on business care priorities, ultimately underpinning the delivery of outstanding person-centred care.

Beyond data residency: The real meaning of AI sovereignty

AI sovereignty has quickly moved from being a policy discussion to a business priority. 

As AI adoption gathers pace across government, critical national infrastructure and highly regulated sectors, the conversation is shifting. It is no longer just about what AI can do, but who controls it, how resilient it is and what happens when technology, suppliers or geopolitical circumstances change. 

Recent global events have reinforced a question many leaders are now asking: how do you embrace the latest advances in AI without becoming dependent on technology not fully in your control? 

Too often, the answer starts and ends with data residency. 

Where data is stored certainly matters, but it is only one part of the picture. AI sovereignty is much broader. It means retaining control over the data, infrastructure, operations, governance and increasingly the AI models that underpin critical services. More importantly, it gives organisations the confidence that they can continue to operate, adapt and evolve without being tied to a single supplier or jurisdiction. 

Impact of choice in AI sovereignty

That does not mean turning away from global technology providers. 

The goal is not isolation or building everything from scratch, but preserving choice. Organisations should be able to decide where workloads run, how services evolve and how data is managed, while still benefiting from the pace of innovation delivered by leading cloud and AI platforms. 

The decisions that shape that flexibility are often made long before the first AI model is deployed. 

Building sovereignty into architecture

Architecture plays a central role. Modular, standards-based platforms make it far easier to replace or introduce individual services without disrupting the wider environment. Open APIs, common identity standards and interoperable integration patterns reduce unnecessary dependency and leave room to adapt as technology, policy and operational requirements change. 

Data portability

The same thinking applies to data. 

For most organisations, data is their most valuable asset. Keeping it portable, accessible and governed through open formats and clear ownership models helps avoid unnecessary lock-in while making future migrations or technology changes far less complex. 

Identity & access

Identity deserves the same attention. It should be treated as a strategic capability rather than something that simply supports the platform. Using recognised standards gives organisations greater control over authentication and access without creating unnecessary reliance on proprietary services. 

Cloud-native flexibility

Cloud-native engineering and containerisation also support these objectives. Applications designed to run consistently across public cloud, private cloud, hybrid environments or on-premises infrastructure provide greater resilience and flexibility. These are not always the most visible design decisions, but they often determine how adaptable an AI platform will be in five or ten years’ time. 

Governance is as important as technology

Technology, however, is only part of the answer. 

One of the biggest challenges we see is moving beyond successful AI pilots. Many organisations have demonstrated value in controlled environments but struggle to scale because governance has not kept pace. Without clear accountability, robust controls and well-defined operating models, production deployment becomes significantly harder. 

That is why AI sovereignty is not just about infrastructure. It also depends on governance, security and assurance being built into the delivery process from the outset. This is particularly important in government, defence, law enforcement and other regulated sectors, where trust, compliance and resilience are non-negotiable. 

How to put AI sovereignty into practice

It starts by identifying which data, services and capabilities must remain under your control. From there, technology choices should support interoperability, portability and long-term flexibility rather than creating new dependencies. 

Open standards, modular architectures and cloud-agnostic deployment approaches all contribute to that outcome. Just as importantly, governance should be embedded from day one, with appropriate security controls, model oversight, auditability and clear accountability built into the operating model rather than added later. 

Designing for AI sovereignty with CACI

The organisations making the greatest progress are not choosing between innovation and control. They are designing for both. 

That is where CACI brings practical experience. Working across secure cloud, data platforms, digital identity and AI-enabled transformation, customers can build environments that are resilient, interoperable and governed from the start with our support. 

As these conversations mature, sovereign cloud capabilities are becoming an increasingly important part of the wider strategy. CACI’s role as an AWS European Sovereign Cloud (ESC) launch partner reflects our commitment to helping customers adopt AI and cloud services while maintaining greater control over critical workloads, data and compliance requirements. 

AI sovereignty should not be seen as a barrier to innovation. When organisations build control, governance and interoperability into their platforms from the outset, they are in a much stronger position to confidently adopt new technologies and adapt as the landscape continues to evolve. 

AI in production: Why foundations start with outcomes

AI adoption is now widespread across most enterprises, but meaningful, scaled impact remains relatively rare.

Across finance, marketing, operations and technology teams, organisations are using AI to improve forecasting, automate processes, accelerate content creation and support decision-making. Yet despite this momentum, many still struggle to move beyond isolated successes and deliver consistent value across the business.

The challenge is rarely the technology itself. More often, organisations rush to pilot tools and models before defining the outcome they are trying to achieve. In many cases, they also make assumptions about what their foundations should look like, centralising data, building platforms or designing architectures before they fully understand the problem they are trying to solve. The most effective foundations are rarely fixed; they emerge from a clear understanding of the outcome being pursued.

This matters because AI is not a single capability. Different approaches solve different problems, introduce different risks and place different demands on data, governance and operating models. The foundations needed for a predictive model are not the same as those required for a generative assistant or an agentic system capable of taking action across multiple platforms.

Trust sits at the centre of all of this. AI only delivers value when people trust the outputs, understand how decisions are being made and have confidence in the data, governance and security that sit behind them. The organisations seeing the greatest success start with the outcome, choose the right approach and build the foundations to support it. This article explores what those foundations look like in practice.

Choosing the right AI approach for your outcome

AI is often spoken about as though it is a single capability. In reality, it is a collection of different techniques, each designed to solve different problems and deliver different outcomes.

The organisations seeing the most success with AI don’t start by choosing a model. They start by defining the outcome they want to achieve, then selecting the approach best suited to delivering it.

While there are many different flavours of AI, the three below represent some of the most common approaches used in organisations today. For a deeper dive into the wider AI landscape and real-world use cases, see our AI Playbook, written by CACI’s Director of Data & AI Ethics, Sue MacLure.

AI approachWhat it doesExample business outcomesFoundation requirementsKey governance & control considerations
Predictive AI Uses historical data to forecast future outcomes.Predicting customer churn, forecasting demand or identifying risk.Consistent, high-quality historical data with clear definitions and strong data quality controls.Data quality, bias monitoring, explainability and auditability of decisions.
Generative AI Creates new content or enables natural language interaction with information.Internal knowledge assistants, summarising documents, generating marketing content.Well-structured, trusted information sources and effective grounding mechanisms to improve accuracy.Output governance, hallucination management, security of sensitive information and responsible usage policies.
Agentic AI Coordinates systems, data and tools to take actions on behalf of users.Automating workflows, resolving customer requests or orchestrating business processes.Reliable integrations, access to multiple systems and clearly defined operational boundaries.Action authorisation, monitoring, human oversight, security controls and accountability for decisions.

These differences matter because each approach places different demands on the organisation.

A predictive model built on poor-quality data will produce unreliable forecasts. A generative AI assistant without access to trusted information may produce convincing but inaccurate responses. An agentic system operating without appropriate controls can take actions that create operational or security risks.

The organisations that scale AI successfully recognise these differences early. They don’t apply a single blueprint. Instead, they choose the right approach for the outcome they want to achieve and design the foundations, governance and operating model around it.

Designing the right data foundations for AI

There is no single blueprint for preparing data for AI. The way data should be structured, accessed and managed depends on both the outcome you are trying to achieve and the characteristics of the data itself.

Some information lends itself to centralisation and reuse. Other data is more valuable when it remains close to the source. Understanding the difference is key to designing data foundations that support AI effectively.

Data architecture is not one-size-fits-all

One of the biggest misconceptions in AI is that there is a single set of foundations that every organisation should build towards. In reality, the right data architecture depends on what you are trying to achieve. The outcome should shape the foundation, not the other way around.

Some benefit from being highly structured, unified and optimised for reuse. Others rely on data that changes too frequently or is too complex to move and store efficiently in one place.

In these cases, the focus should not be on centralising data, but on enabling secure, governed access to it where it already exists.

Designing your data architecture becomes a set of deliberate choices:

  • What outcomes are you trying to deliver?
  • Which data is critical to achieving them?
  • What needs to be standardised and shared?
  • What is best accessed directly from source systems?
  • How will models interact with that data in a secure and controlled way?

Designing for different data behaviours

The way data behaves should directly influence how it is structured and accessed. If, for example, a customer uses an airline’s AI assistant to ask about an existing booking, the underlying data is relatively stable. It can be standardised, catalogued and surfaced through a semantic layer, allowing the model to respond quickly, accurately and at low cost.

However, if that same customer asks, “How much will it cost to fly to Lagos next week?”, the answer depends on constantly changing inputs such as pricing, availability and demand.

In this case, centralising the data provides little value. Attempting to store and cache it introduces complexity and risk without improving accuracy. Instead, the priority shifts to enabling secure, real-time access to source systems, with the appropriate controls in place to ensure data is used safely and correctly.

Trust, governance and control are architectural decisions

What was once used by a small number of specialists becomes available to many users and systems, often at much higher speed and frequency. Without the right controls, this can quickly expose issues that were previously hidden.

For example, teams working closely with data often build informal safeguards, manually correcting inaccuracies or filtering out known issues. When AI automates those processes, those safeguards disappear. The same data is now consumed at scale, increasing the risk of errors, bias or misuse.

This is where governance becomes critical.

Data needs to be:

  • catalogued, so it can be found and understood
  • labelled, so its meaning, sensitivity and usage are clear
  • traceable, so it is possible to see where it came from and how it has changed
  • controlled, so access is appropriate and auditable

Without this, AI systems cannot be trusted, regardless of how well the model performs. Read more in our insight report on how clean data enables good AI.

Creating a shared understanding of “truth”

When multiple teams and systems rely on the same data, consistency becomes critical.

A “customer” in marketing may not mean the same thing in finance. Without clear definitions, models will produce inconsistent outputs, undermining trust and making results difficult to act on. Approaches such as semantic layers and structured data models help address this by creating a shared, governed view of key data assets, while still allowing for context where needed.

The goal is not to unify everything. That is slow, costly and rarely achievable.

Instead, it is about:

  • identifying high-value data
  • creating clear definitions and ownership
  • and enabling access through well-governed integration

People and operating model

As AI takes on more of the execution, roles shift from doing the work to directing it, interpreting outputs and taking accountability for decisions. AI removes tasks, but not responsibility.

This creates a fundamental change in how organisations need to operate. Teams are no longer just delivering outputs, they are working alongside systems that generate, recommend or take action on their behalf. That requires new skills, clearer ownership and different forms of oversight, with the level of control depending on the type of AI being used and the outcomes it is supporting.

Trust is what enables adoption

For AI to be used at scale, people need to trust it. That trust is not created through mandates or targets. It comes from confidence that the system is:

  • using the right data
  • producing reliable outputs
  • operating within clear boundaries

Without that, adoption will always be limited. People will either avoid using AI altogether, or use it cautiously and inconsistently, which limits its impact.

This is where governance and transparency play a critical role. When people can understand how a system works, where its data comes from and how decisions are made, they are far more likely to engage with it confidently.

Ways of working must evolve

One of the most common failure points in AI adoption is that organisations introduce new technology, but keep existing ways of working.

AI works best in environments where:

  • teams are cross-functional
  • data, technology and business functions collaborate closely
  • accountability for outcomes is clearly defined

Without this, AI remains isolated in pockets of the organisation rather than becoming part of how it operates day to day.

This often requires structural change. Not necessarily to reduce headcount, but to align skills and roles to where value is created. In many cases, it is about redeploying people, not replacing them.

This is a shift, not an optimisation

AI can deliver immediate value by helping organisations do things faster. But the longer-term opportunity lies in reimagining how work is designed, delivered and experienced.

When Thomas Edison invented the lightbulb in 1879, candlemakers didn’t look for ways to use it to produce candles more efficiently. They recognised that it required a fundamental shift in how light was created and used.

The same applies to AI. If organisations focus only on optimising existing processes, they will limit its potential. The real opportunity comes from stepping back and asking what work should look like when AI is part of the system.

With only 12% of organisations feeling prepared to adopt AI in day-to-day operations, it’s clear that very few have fully figured it out. As AI continues to evolve at pace, so too do the ways it can be applied. But those that are already thinking in this way, starting with the opportunity rather than the constraint, are the ones best positioned to move beyond incremental gains and realise meaningful, scaled impact.

Ultimately, AI only delivers value when it is embedded into how the organisation operates. That requires people to trust it, understand it and have clear accountability for how it is used.

AI success looks different across the organisation

Different parts of the business will define AI success differently.

For technology leaders, success often looks like scalable, secure systems that can be trusted to run reliably. For finance teams, it is about cost control, efficiency and measurable return. Data leaders focus on quality, governance and ensuring outputs can be relied upon. Marketing teams may look to AI to personalise experiences, reach the right audiences and improve campaign performance (for more on how AI can help you achieve this, see our whitepaper on AI decisioning).

A marketing team cannot deliver effective personalisation without access to well-structured, trusted data. Finance cannot measure ROI without visibility into how models are performing and what they are costing to run. Technology teams cannot scale AI safely without strong governance, security and integration in place.

This is where organisations often get stuck. AI initiatives are prioritised within individual functions, but the underlying foundations are shared. When those foundations are weak or inconsistent, every use case is affected, regardless of where it sits in the business.

The organisations that succeed recognise this early. They align around common foundations, even as teams pursue different outcomes. In doing so, they create an environment where AI can be applied consistently, safely and at scale.

Turning AI into something your business can rely on

Getting AI into production is not a technical milestone. It is an organisational one.

The challenge is rarely a lack of capability. It is knowing how to apply that capability in a way that aligns with business outcomes, works within real-world constraints and can be trusted at scale.

This is where the difference between experimentation and impact becomes clear. Successful organisations do not treat AI as a bolt-on capability. They design it into how their data is structured, how their systems operate and how their people work.

At CACI, this is the approach we bring to AI. Built on decades of data expertise, we combine deep technical specialism with a practical understanding of how businesses operate. That means going beyond models and tools, taking the time to understand the outcomes you are trying to achieve and designing the architecture, governance and operating model to support them.

Crucially, this is done with trust at the centre. AI only delivers value when people understand it, adopt it and have confidence in how it is being used. That requires strong data foundations, clear governance and a human-centred approach to how systems are designed and deployed.

Because ultimately, successful AI is not about implementing technology. It is about embedding it in a way that works for your people, your processes and your long-term goals. To learn more about how CACI can help your organisation architect AI for scale, get in touch to start the conversation.

Rethinking “buy, not build” in the age of Agentic AI

How agentic AI is redrawing one of tech’s most enduring rules of thumb

Agentic AI is beginning to change how software is developed, particularly in how quickly teams can generate and iterate on code. While this has clear implications for cost and speed, it does not remove many of the underlying complexities of software delivery, and in some cases introduces new ones.

For decades, organisations defaulted to “buy, not build” because building was costly and slow, while off-the-shelf software became more mature, reliable and easier to adopt. That balance is now beginning to shift. Agentic AI is making it faster and, in some cases, more cost-effective to create bespoke solutions, starting to change the economics of building software.

However, adopting AI at scale is proving more complex than the technology itself. Many organisations are experimenting with AI-assisted development, but scaling it remains challenging due to skills gaps, governance requirements, trust and integration into existing engineering practices.

The Buy vs Build reality is more nuanced: while AI can accelerate parts of development, it has not replaced the need for strong operating models, domain expertise or human oversight. The advantage comes from combining AI speed with human expertise, not replacing one with the other, a theme explored further in our AI playbook.

Why “buy” won

To understand whether the Buy vs Build rule is changing, you first have to understand why it arose. The instinct is often to frame it as a cost argument: developer time is expensive, so buying a ready-made product is cheaper. That is true, but it undersells the real reasons.

Developer scarcity drove up opportunity cost

Every engineer hour carried an opportunity cost. Building internal tools meant not building something else. The constraint wasn’t just capacity, but trade-offs: investing in non-differentiating systems often came at the expense of innovation or competitive advantage. “Build versus buy” was really a question of value.

Mature products embedded decades of domain knowledge

A well-established CRM (Customer Relationship Management), ERP (Enterprise Resource Platform) or risk platform is not just software. It is the accumulated wisdom of thousands of client implementations, regulatory cycles, edge cases and hard lessons. In these cases, the code mattered much less than the years of accumulated wisdom built into the product.

Operational burden was real

Before cloud-native infrastructure matured, owning a codebase meant owning a significant operational liability alongside it.

Requirements compromise was an acceptable trade-off

Bending processes to fit the software was not ideal, but often a reasonable trade-off because the alternative was too costly.

The result was “buy” becoming the default and “build” only winning when the capability in question was genuinely core to competitive differentiation, and even then, only if the organisation had the engineering depth to sustain it.

Crucially, “buy” never had to justify itself. It was the default. The burden of proof sat entirely with anyone proposing to build, much like the dynamic seen with “cloud-first” strategies, where cloud deployments sailed through architectural governance unchallenged, and it was only on-premise proposals that faced scrutiny.

What Agentic AI changes

Agentic AI – the class of systems that can plan, write code, test it and iterate with increasing levels of automation – directly affects the most visible cost in the build equation: the writing of the code itself.

As tooling matures and agents become more capable of managing their own context and quality gates it shifts the role of engineers from pure builders to orchestrators of AI-driven development.

This shift does not simplify the role of engineering teams, it expands it.

Engineers are increasingly required to work across architecture, governance, security and compliance, often in closer collaboration with legal, risk and business teams.

But what are the consequences for engineering leaders?

Greenfield bespoke tooling becomes economically viable again

Internal tools, data pipelines, workflow automation, custom reporting layers, the kind of work that reliably lost the buy-versus-build analysis on cost grounds for the past fifteen years, can now tip the other way, becoming economically attractive for organisations that previously lacked the scale, budget or technical capacity to justify building in-house.

However, this shift should not be mistaken for simplicity. Much of the cost and complexity of software delivery has never sat purely in writing code. Activities such as requirements gathering, low-level design, security and compliance, efficiency, integration with existing systems, deployment, user adoption and change management remain significant and often more challenging than the development itself.

This is particularly true in existing enterprise environments, where systems are designed for interoperability, resilience and regulatory compliance. While AI makes it quicker to purely generate code, it does not shortcut the design, architecture and contextual elements that has always made software development challenging and exacting.

The cost of requirement compromise falls

Buying off-the-shelf software always meant accepting a trade-off: your processes bent to the software’s logic, not the other way around. Agentic AI changes that calculus. When you can build to your exact requirements at a fraction of the previous cost, that compromise becomes much harder to justify.

Iteration replaces specification

AI-assisted development changes the nature of the build process itself. You no longer need a complete, validated specification before you start. You build, observe and refine cycles that were previously too expensive except for the highest-priority systems.

Why “buy” does not collapse

Despite these shifts, it is important to recognise that many of the original reasons for buying software remain unchanged.

The case for buying has been challenged, but the need has not disappeared. The strongest arguments for buying were never really about code in the first place.

Compliance and security hardening cannot be generated

A mature SaaS product carries years of penetration testing, third-party audits, SOC 2 certifications, GDPR machinery and incident response history. An AI agent can generate code; it cannot generate the audit trail, vendor liability or the enterprise trust that took years to earn.

Ecosystem and integration value is sticky

Established platforms and ecosystems remain the logical choice to “buy” because everything else connects to them. That network effect does not erode simply because building has become cheaper.

Deep domain knowledge still requires human time to reconstruct

Think of a credit risk engine, a tax calculation platform or a clinical trial management system. The rules encoded in that software represent decades of regulatory interpretation, institutional learning and hard-won edge-case handling. A prompt alone does not reconstruct that and attempting to do so carries real risk.

AI-generated code requires stronger human oversight, not less

AI can accelerate development, but it does not replace the need for engineering judgement. Someone still needs to define the architecture, set quality standards, manage dependencies and make the call when AI generates something that looks right, but is not.

What changes is the nature of the role. Engineering teams shift from writing every line of code to directing, validating and governing AI-generated output. That requires new disciplines: clearer architectural guardrails, stronger review practices and teams trained to work effectively with AI systems.

Organisations that treat AI as a shortcut around engineering rigour will see the cost return quickly, in the form of rework, security gaps or fragile systems. The advantage comes from combining AI speed with human oversight, not replacing one with the other.

The “buy” vendors are using the same tools

The gap does not close only from the build side. SaaS providers are accelerating their own development with exactly the same AI capabilities. The competitive starting point keeps moving.

The emerging reframe of “buy not build”

The result is not a reversal of the buy-versus-build dynamic, but a more nuanced version of it.

The old mantra was binary. The new reality is a spectrum, and a better way to frame it is:

Build what differentiates you. Buy the commodity. The principle remains, but agentic AI has moved the boundary. Understanding what to build, buy and how to do both in a scalable, secure way is where the real challenge exists. Many organisations are not yet equipped to make those decisions confidently.

Previously, “what differentiates you” was a very narrow slice. The cost of building meant only truly proprietary capabilities, core algorithms or unique models, could justify investment, with everything else treated as commodity.

Agentic AI expands that slice. Capabilities that were previously too costly to build, such as internal tooling, data pipelines or workflow automation, are now worth revisiting.

However, the “always buy” category remains where value is not in the code itself: regulated platforms, established ecosystems and software underpinned by deep, embedded domain knowledge that is costly and risky to replicate.

The nuance worth preserving

It would be a mistake to read this as a simple reversal, “build, not buy” for a new era. The discipline behind the old mantra still matters and some of it deserves to survive. The question remains “Why does this need to be bespoke?” The answer just has a lower bar to clear than it did before.

The mantra is not dead; it’s being renegotiated.

Of course, it would be a mistake to think of this as a binary option. Agentic AI development is blurring the lines as to what Buy really means, and what Build is in practice. Increasingly, organisations are less concerned with whether something is “built” or “bought”, and more focused on delivering outcomes.

In practice, this means combining AI-generated code, cloud-native resources, third-party platforms and internal components to achieve the desired result, rather than treating build and buy as separate decisions. Blending components and capabilities into a single platform.

The middle ground

There is still a demonstrable need to utilise buy components within a “build first” environment, especially where there are specific requirements and needs around security, governance, perform, context and compliance.

However, there is also a growing middle ground, where organisations combine custom development with proven accelerators and platforms. These approaches retain flexibility while reducing risk, particularly in regulated or complex environments.

For example, accelerators such as CACI’s Jezero enable organisations to accelerate delivery while embedding proven patterns around security, governance and architecture.

This allows teams to take advantage of AI-assisted development without starting from scratch or introducing unnecessary risk.

How organisations should respond safely and effectively

  • Reopen “build versus buy” decision-making: The economics have changed, meaning areas that were previously considered a commodity should be reassessed.
  • Establish governance for AI-generated code: Define quality gates, dependency policies or any architectural guardrails.
  • Design an AI-ready operating model: AI-assisted building is risky without the right operating model and teams skilled in directing and governing AI outputs in place.
  • Partner with a trusted specialist: Most organisations lack the governance, architecture and compliance frameworks to scale AI effectively, which is where a trusted partner can make all the difference.

Agentic AI is quickly becoming part of the standard development toolkit. While it creates clear efficiencies, it also demands stronger governance, critical thinking and well-defined guardrails to ensure systems remain secure, maintainable and fit for purpose.

At CACI, we’ve approached this shift with a focus on control as much as capability. We have embedded defined patterns, development standards and governance controls into how AI-assisted development is used, ensuring that code generated through these approaches aligns with security, architectural and operational requirements from the outset.

Understand what to build, what to buy and where Agentic AI creates real advantage

The build-versus-buy boundary is shifting, but changing that boundary without the right controls introduces as much risk as opportunity.

Agentic AI can reduce the cost of building. It does not reduce the consequences of building the wrong thing, in the wrong place, without the right governance. Navigating this shift requires more than new tools, it requires critical thinking, strong architecture, and deep technical and domain expertise.

At CACI, we help organisations re-evaluate build-versus-buy decisions in light of Agentic AI, not just from a development perspective, but across operating models, governance and long-term ownership. That means understanding where AI genuinely changes the economics of building, how to integrate it effectively into software engineering processes, and where proven accelerators can de-risk and accelerate delivery.

For organisations looking to explore these challenges in more detail, we’ve also captured insights from our recent Architecting the AI-ready enterprise breakfast briefing, to provide a practical view of what adoption looks like in reality.

Ultimately, this is about combining the best of both approaches, AI-assisted development, established platforms and learned experience of complex environments, to build differentiated capabilities in a way that is scalable, secure and sustainable.

This is not about building more; it’s about building where it matters, and knowing where it does not. If you are reassessing how Agentic AI should shape your technology strategy, speak to our specialists to explore how to move forward with clarity and control.